Scaling Physical AI
Accelerating LLM inference for
Physical AI
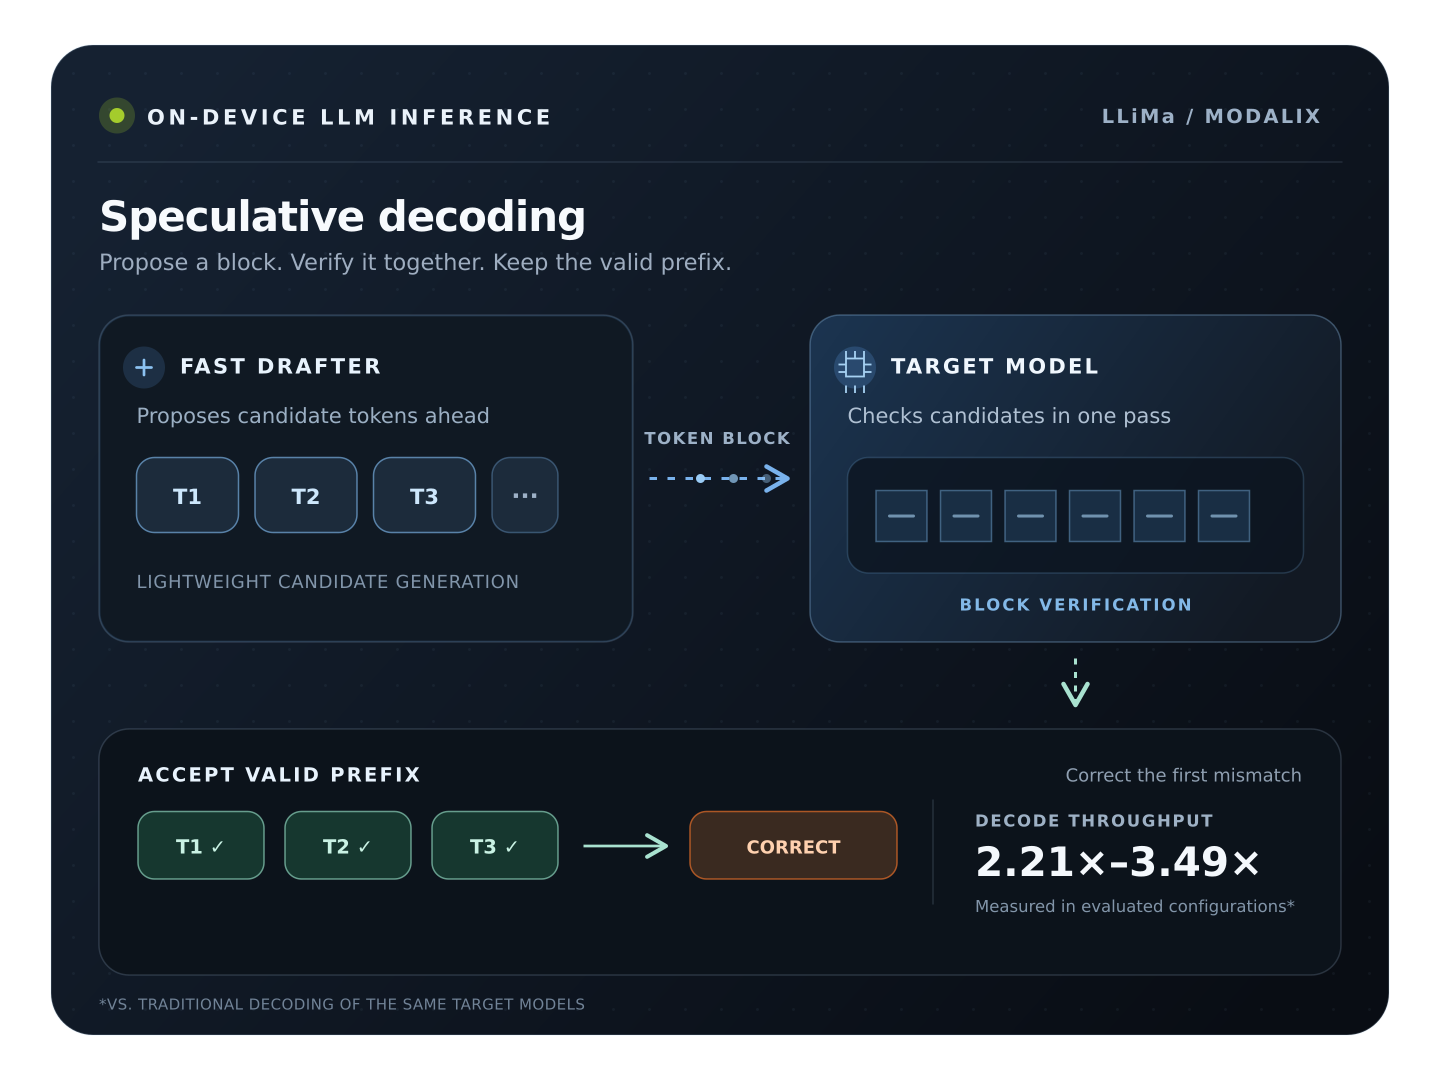
Speculative decoding on SiMa.ai Modalix MLSoC helps robotics engineers run responsive, efficient LLMs on-device.
EAGLE3, DFlash and Gemma 4 MTP accelerate generation and actionable responses while lowering compute energy per request.
-
Up to 3.5×
faster token generation
at comparable power consumption
-
Up to 2.06×
faster actionable responses
for responsive on-device AI
-
51% lower
compute energy per request
with speculative decoding